Metrum AI is announcing support for NVIDIA DGX Spark in Metrum Insights, a platform for benchmarking model, pipeline performance, and accuracy. This integration makes it easier to measure end-to-end throughput, latency, cost efficiency, and evaluation quality across modern workloads.
"Early results on NVIDIA DGX Spark show strong standalone performance, even against server-class GPUs, translating into lower Tokens-Per-$ on state-of-the-art SLMs. Combined with Metrum Insights' automated evaluations and performance analytics, customers can make smarter deployment decisions, faster."
- Chetan Gadgil, CTO, Metrum AI
Metrum Insights and NVIDIA DGX Spark
-
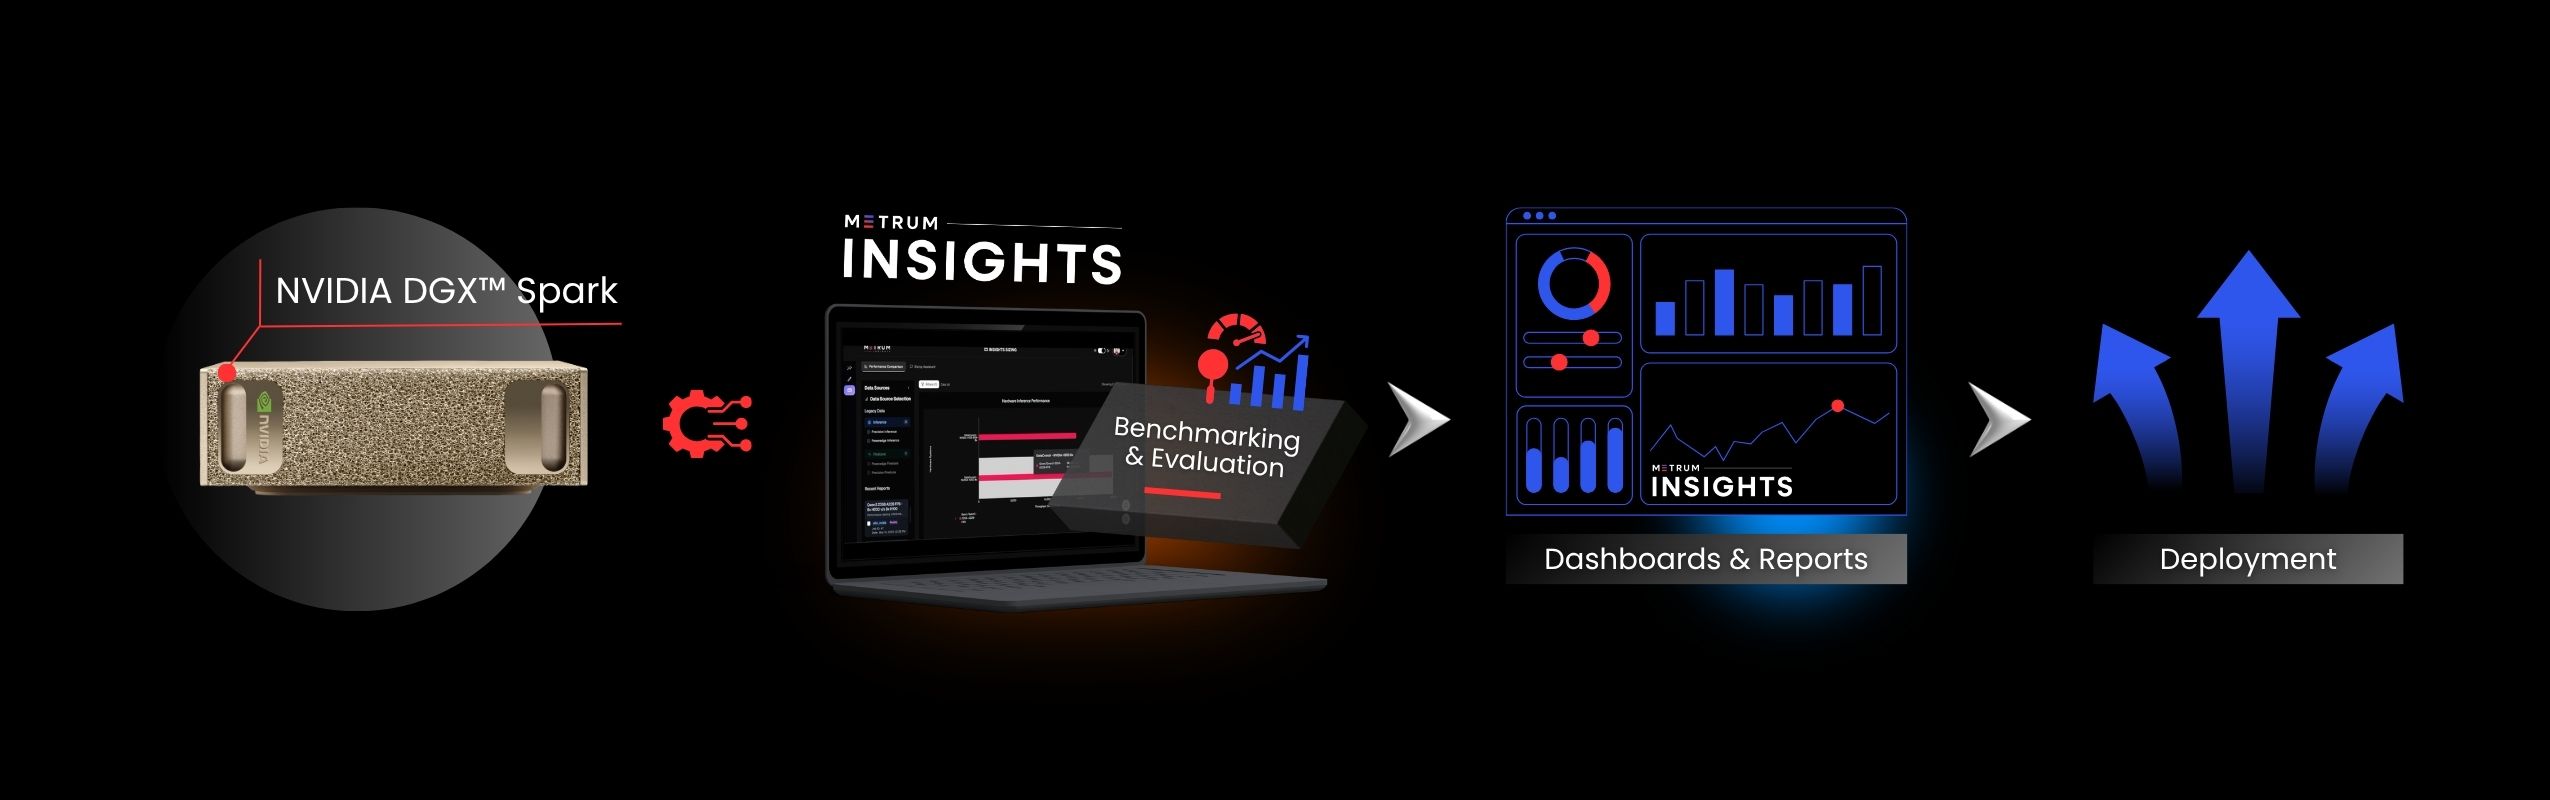
Development to production: Metrum Insights integrates with DGX Spark to provide a single environment for benchmarking and evaluation, including fully self-contained on-premises deployments.
-
Higher throughput, lower cost: Powered by the NVIDIA GB10 Grace Blackwell Superchip, DGX Spark increases tokens per second and reduces cost per token with built-in cost modeling.
-
Comparable results: Standardized harnesses for NVIDIA NIM, vLLM, SGLang, LoRA fine-tuning, and RAG pipelines enable apples-to-apples metrics across hardware, models, and configurations.
-
Full-stack visibility: Track utilization, power, and memory alongside model-quality metrics in one place.
-
LLM/VLM workflows: Evaluate inference across varying concurrency and input/output token lengths to validate performance and accuracy on leading models.
How It Works
-
Target selection: Choose DGX Spark in project settings. Metrum Insights auto-detects GPU topology, mixed-precision features, and recommended runtime flags.
-
Standard evaluations: Run suites covering latency, throughput, Tokens-Per-Watt, accuracy, and power with flexible benchmark configurations and industry-standard datasets.
-
Dashboards: Monitor Tokens-Per-Watt, p95 latency, and accuracy deltas in unified dashboards; export reports for procurement and capacity planning.
Early Results
-
Compact performance: Portable yet powerful, delivering near server-class performance in a compact design
-
Accuracy maintained: Mixed precision plus tuned quantization settings.
-
Lower cost per token: Improved Tokens-Per-$ for AI Agents, RAG, and fine-tuning, enabling larger context windows and faster responses at the same spend, deployable without special facility requirements.
Getting Started
-
Existing users: DGX Spark is now available as a hardware target in the latest Metrum Insights release.
-
New to Metrum? Start a trial project, choose an LLM, and run your first DGX Spark benchmark in minutes.
Metrum Insights provides actionable insights to help teams ship faster and more cost-effective systems. With NVIDIA DGX Spark support in Metrum Insights, you can quantify gains and put them into production.
Contact: contact@metrum.ai